Milliseconds Into Money: Quantifying the Performance Drag Hidden Inside Your Enterprise Cloud Stack
Photo: Strubbl, CC BY-SA 4.0, via Wikimedia Commons
In most enterprise budget conversations, productivity losses show up as headcount gaps, missed deadlines, or morale surveys. Rarely does anyone pull up a dashboard and point to a number labeled cloud latency cost. Yet for organizations running complex, multi-tool cloud environments, that invisible line item may be one of the largest untracked expenses on the books.
The challenge is not that the problem is obscure. It is that the damage accumulates in increments too small to trigger an alert—a two-second file sync delay here, a five-second API handshake there, a dashboard that takes just long enough to load that the user opens a second tab and loses focus. Multiply those moments across a workforce of thousands, and the math becomes uncomfortable quickly.
The Anatomy of Cloud Performance Loss
Enterprise cloud slowdowns rarely have a single cause. More often, they result from a layered combination of factors that interact in ways no single vendor ever fully anticipates.
Latency is the most commonly cited culprit, and it is worth distinguishing its forms. Network latency—the time it takes data to travel between a user's device and a cloud server—is heavily influenced by geographic distance, routing inefficiencies, and ISP-level congestion. Application latency, by contrast, stems from how well a platform's codebase handles concurrent requests, database queries, and rendering logic. Both are measurable. Neither is inevitable.
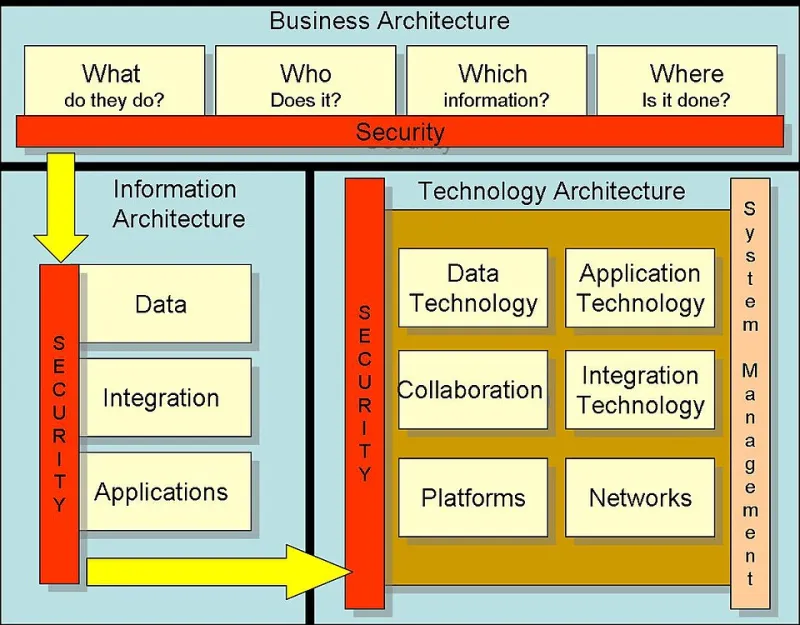
Integration delays represent a subtler but equally costly category. When your document management system must authenticate through an identity provider, pull permissions from a directory service, and then call a storage API before a file opens, each handshake adds time. In a well-architected stack, these calls happen in parallel and resolve in under a second. In a typical enterprise environment cobbled together over several years of procurement decisions, they frequently do not.
Throughput bottlenecks emerge when the volume of simultaneous operations exceeds what a platform's infrastructure can handle gracefully. This is particularly common during peak hours—Monday mornings, fiscal quarter closes, all-hands meeting preparation periods—when the entire organization reaches for the same tools at once.
Building a Diagnostic Framework
Before optimization can begin, measurement must. IT leaders who approach cloud performance without baseline data tend to chase symptoms rather than causes. A structured diagnostic framework should address three distinct layers.
Layer one: End-user experience monitoring. Deploy real-user monitoring (RUM) tools that capture actual load times, interaction delays, and error rates as experienced by employees—not as reported by the vendor's infrastructure dashboard. The gap between server-side performance metrics and client-side experience is often significant, and it is the client-side number that determines whether your workforce is productive.
Layer two: Integration path mapping. Document every API call, authentication handshake, and data transfer that occurs during your most common workflows. Tools that visualize service dependency chains can reveal where requests are queuing, timing out, or being retried unnecessarily. Many organizations discover that a single misconfigured middleware component is responsible for a disproportionate share of their total delay.
Layer three: Workforce impact quantification. This is where IT strategy intersects with business finance. Using time-tracking data or workflow analytics, estimate the average number of performance-related friction events per employee per day. Assign a conservative time cost to each event—typically between five and thirty seconds depending on the action—and multiply across your workforce and average fully-loaded labor cost. The resulting figure is your productivity tax baseline, and it gives IT leadership a defensible number to bring into budget conversations.
Common Optimization Levers
Once diagnostic data is in hand, most enterprise environments have several high-return optimization opportunities available without requiring a full platform migration.
CDN and edge caching strategies can dramatically reduce latency for geographically distributed teams. If your organization has significant employee populations in regions distant from your primary cloud region—common for US enterprises with teams in the Mountain West, Alaska, or Hawaii—routing traffic through edge nodes closer to those users can cut load times by thirty to fifty percent for static assets and frequently accessed data.
Asynchronous integration architecture reduces the sequential dependency problem. Rather than requiring each integration handshake to complete before the next begins, well-designed middleware platforms allow multiple calls to run concurrently. Migrating even a handful of critical workflows to asynchronous patterns can produce measurable improvements in perceived responsiveness.
Throttling and rate limit audits are frequently overlooked. Many enterprise cloud subscriptions include API rate limits that, at the time of contract signing, seemed more than sufficient. As usage grows and integrations multiply, those limits become invisible ceilings. Regularly auditing rate limit consumption—and renegotiating or upgrading tiers where necessary—prevents a class of performance degradation that is entirely contractual rather than technical.
Scheduled maintenance windows and off-peak workload shifting address throughput bottlenecks at the infrastructure level. Batch processing jobs, report generation, and large data exports should be scheduled during low-usage periods whenever business requirements allow. This is an operational discipline rather than a technical fix, but its impact on peak-hour performance is consistently underestimated.
Making the Case Internally
Perhaps the most strategically important step in addressing cloud performance is reframing the conversation for executive audiences. IT leaders who present performance optimization as a technical project compete for budget against other technical projects. Those who present it as a recoverable productivity cost—backed by the quantification methodology described above—compete against operational inefficiencies, which tend to command more sustained attention at the C-suite level.
A workforce of five hundred employees losing an average of twelve minutes per day to cloud performance friction represents roughly one thousand hours of lost productive capacity every week. At a blended labor rate of sixty dollars per hour, that is sixty thousand dollars per week—or more than three million dollars annually—in value that is currently being absorbed as overhead rather than channeled into output.
That figure is not an alarm. It is a starting point. With the right diagnostic foundation and a prioritized optimization roadmap, most enterprises can recover a meaningful fraction of that cost within a single fiscal quarter.
The cloud was adopted to accelerate work. When it slows work instead, the gap between promise and performance deserves the same analytical rigor your organization applies to any other material business cost. The tools to measure it exist. The strategies to address it are well-established. What remains is the organizational will to treat latency not as a technical inconvenience, but as a line item with a balance due.